LLM Evaluation You Can Trust: Catching a Harness That Lied
Lynon Solutions
Published
0
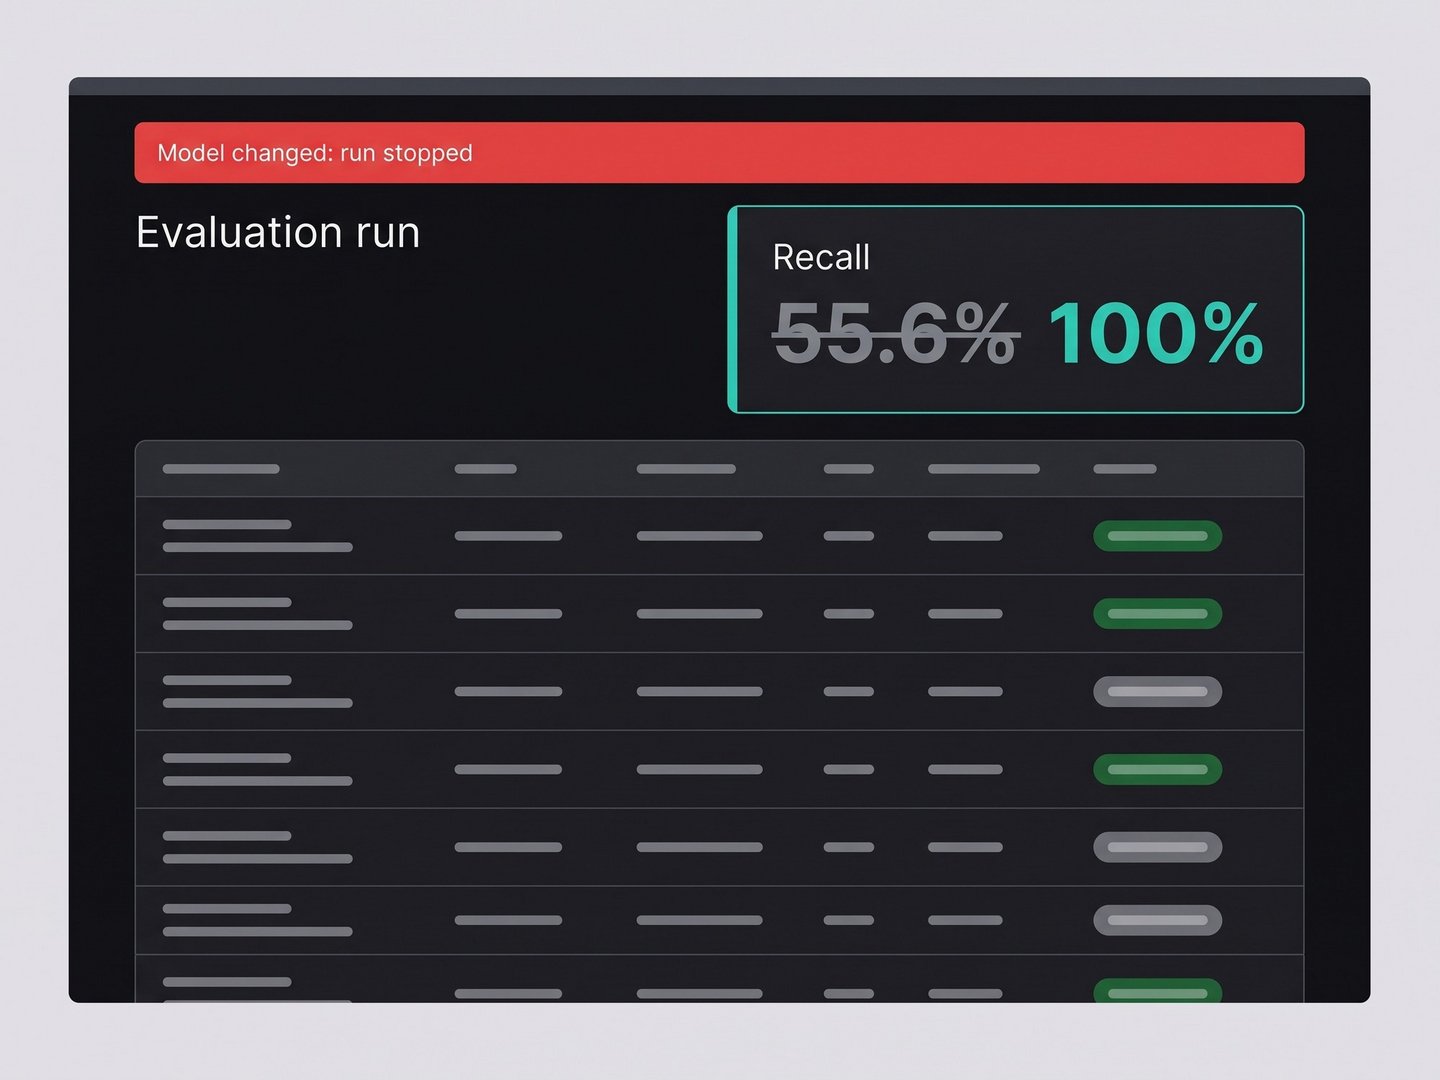
Our evaluation of the retriever, the AI’s search step, reported low recall. Recall is the share of correct records that the retriever returns. But the retriever returned every correct record. The test query did not apply the production visibility rule. So the evaluation expected records that the retriever could not see.
The run showed no error. A low number like this sends a team to fix a system that works.
A separate evaluation checks model and prompt changes against a fixed test set in version control. Each run must pass written score limits. Code grades each output by exact match. No AI model grades the output.